
Streaming anomaly detection in Python. PySAD scores each data point when it arrives,
with 16 streaming detectors, calibrated alerts and streaming evaluation.





Documentation · Getting started · How-to guides · Benchmarks · Detectors · API · Try it in Colab
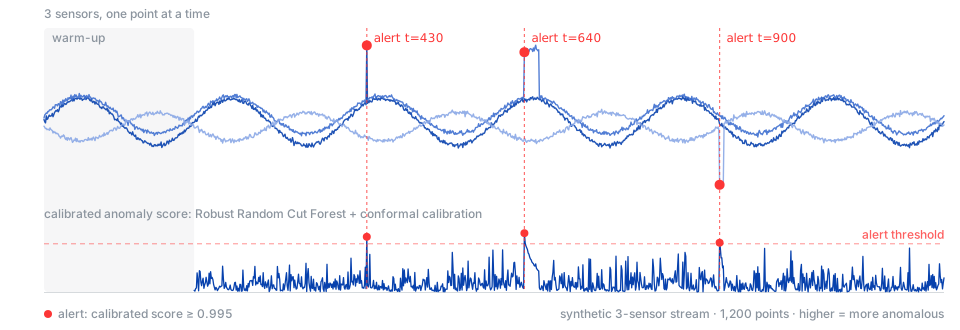
A Robust Random Cut Forest scores three synthetic sensors one point at a time. Conformal calibration converts each score into the fraction of recent scores that it exceeds, and raises an alert at 0.995.
A batch detector needs the whole dataset before it can score a point. A stream does not give you the whole dataset. Points arrive one at a time, the data drifts (its distribution changes over time), and you must decide about each point before the next point arrives. PySAD is built for this setting. More than 60 publications on Google Scholar cite it, and 30+ public repositories on GitHub use it.
|
Every detector learns from and scores one point at a time with |
From robust statistics (MAD, Seasonal Hybrid ESD) to forests, sketches and projections (Half-Space Trees, Robust Random Cut Forest, RS-Hash, xStream, LODA). Each detector cites its paper, and the detector catalog lists its input and memory. |
|
The conformal calibrator converts a raw score into the fraction of recent scores that it exceeds. A threshold such as |
Streamers replay data one point at a time, and 17 labeled benchmark datasets download on first use. Metrics such as AUROC, AUPR, precision and recall update after every point. |
|
Wrap any PyOD detector to train it again on a sliding window of recent points. |
Preprocessors, random projections, score postprocessors, ensemblers and running statistics work with every detector. |
Batch outlier detectors such as PyOD train on a fixed dataset and must train again to use new data. PySAD detectors learn from every point, and PySAD can still run PyOD models on a stream with ReferenceWindowModel. General online learning frameworks such as River treat anomaly detection as one module among many. PySAD is only about streaming anomaly detection: 16 detectors, with calibration, postprocessing, ensembling and evaluation around them.
pip install pysadPySAD supports Python 3.10 to 3.14 on Linux, macOS and Windows. Every detector works after this command, with no optional extras.

Score a stream point by point, and measure the detector while it runs:
import numpy as np
from pysad.evaluation import AUROCMetric
from pysad.models import LODA
from pysad.utils import ArrayStreamer

# A stream of 2,000 points with 4 features. Every 50th point is an anomaly.
rng = np.random.default_rng(42)
X = rng.normal(size=(2000, 4))
y = np.zeros(2000, dtype=int)
y[::50] = 1
X[y == 1, :2] += 3  # the code shifts the anomalies in two of the four features

model = LODA(random_state=0)
metric = AUROCMetric()

for x, label in ArrayStreamer().iter(X, y):
    score = model.fit_score_partial(x)  # score x, then learn from it
    metric.update(label, score)

print(f"AUROC: {metric.get():.3f}") # prints AUROC: 0.960A higher score means a more anomalous point, but raw scores have no fixed scale. The conformal calibrator converts each score into the fraction of recent scores that it exceeds. Continuing the example above, raise an alert when this value is close to 1:
from pysad.transform.probability_calibration import ConformalProbabilityCalibrator

model = LODA(random_state=0)
calibrator = ConformalProbabilityCalibrator(window_size=500)

alerts = []
for t, x in enumerate(ArrayStreamer().iter(X)):
    calibrated = calibrator.fit_transform_partial(model.fit_score_partial(x))
    if t >= 200 and calibrated >= 0.99:  # skip a short warm-up
        alerts.append(t)

# Prints: 20 alerts, 15 of them true anomalies
print(f"{len(alerts)} alerts, {y[alerts].sum()} of them true anomalies")A detector takes one NumPy array per point, so any loop works: a CSV reader, a socket or a message queue consumer.
import json

for message in consumer:  # for example, a Kafka consumer
    x = np.asarray(json.loads(message.value)["features"], dtype=float)
    score = model.fit_score_partial(x)
ArrayStreamer and PandasStreamer replay arrays and DataFrames as streams for experiments.
Install PyOD first with pip install pyod.
from pyod.models.iforest import IForest
from pysad.models.integrations import ReferenceWindowModel

# Train a batch Isolation Forest on the last 200 points, again every 50 points.
model = ReferenceWindowModel(IForest, window_size=200, sliding_size=50, initial_window_X=X[:100])
for x in ArrayStreamer().iter(X[100:]):
    score = model.fit_score_partial(x)
The getting started tutorial explains each step. The how-to guides cover alerts, evaluation, pipelines, seasonal series, production use and custom detectors.
| Your data | Start with | Why |
|---|---|---|
| One series of values with daily or weekly cycles | SeasonalHybridESD |
Removes the cycle. Earlier anomalies in the window have little effect on it |
| One series of values without a strong cycle | MedianAbsoluteDeviation |
Anomalies in the window have little effect on it. It uses only recent values, so it follows drift |
| Several features, first try | LODA |
Fast, has few parameters and learns from every point |
| Features with known value ranges | HalfSpaceTrees |
Constant time per point, scored against the previous window |
| Many features | xStream |
Projects the points to fewer features with hashing |
| Network traffic | KitNet |
Built for network intrusion detection. Gives 0 for the first 100 points by default |
| A PyOD model that you already use | ReferenceWindowModel |
Trains it again on a sliding window |
These starting points come from the design of each method. They are not benchmark rankings. The benchmark gives the results of each multivariate detector on 17 datasets. Compare two or three detectors on your own data, as the guide to choosing a detector shows.
Multivariate
| Class | Method |
|---|---|
xStream |
xStream (Manzoor et al., KDD 2018) |
LODA |
Lightweight on-line detector of anomalies (Pevný, Machine Learning 2016) |
HalfSpaceTrees |
Half-Space Trees (Tan et al., IJCAI 2011) |
RobustRandomCutForest |
Robust Random Cut Forest (Guha et al., ICML 2016) |
RSHash |
RS-Hash subspace outlier detection (Sathe & Aggarwal, ICDM 2016) |
IForestASD |
Isolation Forest on sliding windows (Ding & Fei, IFAC 2013) |
KitNet |
KitNET ensemble of autoencoders (Mirsky et al., NDSS 2018) |
ExactStorm |
Exact-STORM distance-based outliers (Angiulli & Fassetti, CIKM 2007) |
LocalOutlierProbability |
Local Outlier Probabilities (Kriegel et al., CIKM 2009) |
Inqmad |
InQMAD quantum measurement density (Gallego-Mejia et al., ICDMW 2022) |
Univariate
| Class | Method |
|---|---|
SeasonalHybridESD |
Seasonal Hybrid ESD (Hochenbaum et al., 2017) |
SeasonalESD |
Seasonal ESD (Hochenbaum et al., 2017) |
KNNCAD |
Conformalized k-NN anomaly detection (Burnaev & Ishimtsev, 2016) |
RelativeEntropy |
Relative entropy over windows (Wang et al., IM 2011) |
MedianAbsoluteDeviation |
Median absolute deviation over a sliding window (Hochenbaum et al., 2017) |
StandardAbsoluteDeviation |
Running 3-sigma rule (Hochenbaum et al., 2017) |
ReferenceWindowModel and OneFitModel run any PyOD detector on a stream. The detector catalog lists the input, setup and memory of each detector, and the API reference lists every parameter.
PySAD benchmarks its detectors on labeled data. The 10 multivariate detectors run on 17 datasets from the ODDS repository and on 8 real streams with drift. The univariate detectors run on the series of the Numenta Anomaly Benchmark (NAB) and of the UCR archive. Each detector runs once on each dataset, with its default parameters, and scores each point before it learns from it (fit_score_partial).
The benchmark results page shows all the results. The evaluation methodology explains the steps, the metrics and the limits of the results, and the datasets page describes the data. To run the benchmark, use python benchmarks/benchmark.py, as Run the benchmark shows. On each pull request that changes a detector, CI runs a short form of the benchmark and lists the results that moved.
| Stage | What PySAD provides |
|---|---|
| Preprocessing | InstanceStandardScaler, InstanceUnitNormScaler, SeasonalTrendDecomposer, ModifiedSTLResidualTransformer |
| Projection | StreamhashProjector, GaussianRandomProjector, SparseRandomProjector |
| Postprocessing | Running and windowed average, max, median and z-score of scores |
| Calibration | ConformalProbabilityCalibrator, GaussianTailProbabilityCalibrator |
| Ensembling | Average, maximum, median, average-of-maximum and maximum-of-average score ensemblers |
| Evaluation | AUROCMetric, AUPRMetric, PrecisionMetric, RecallMetric, WindowedMetric |
| Streaming data | ArrayStreamer, PandasStreamer, and Data for 17 labeled ODDS benchmark datasets, downloaded on first use |
| Statistics | Running mean, variance, median, min, max, sum and count |
We welcome issues and pull requests, and we aim to reply within a few days. Ask questions and share your projects in Discussions. For a first contribution, choose a good first issue. The contributing guide lists the steps from the first clone to an open pull request.
PySAD follows semantic versioning and trunk-based development. Each change reaches master through a short-lived branch and a pull request that CI checks, and CI runs every example.
Thanks to everyone who has reported a bug, fixed one, or improved the docs.
If you use PySAD in a scientific publication, cite the paper:
@article{pysad,
  title={PySAD: A Streaming Anomaly Detection Framework in Python},
  author={Yilmaz, Selim F and Kozat, Suleyman S},
  journal={arXiv preprint arXiv:2009.02572},
  year={2020}
}
To cite a specific version of the software, use its Zenodo DOI. The DOI 10.5281/zenodo.22983312 always points to the latest release. That page also lists a separate DOI for each release.
PySAD is free software under the BSD 3-Clause License.
If PySAD is useful to you, a star helps other people find it.
To hear about new detectors and releases, choose Watch → Custom → Releases.